September was PACKED with incredible guests having invaluable conversations on my show. ICYMI, today's episode highlights the best bits:
1. The wildly popular data scientist and entrepreneur Aishwarya Srinivasan details which failures a person ought to live through themselves before anyone trusts them to deploy an agent to production.
2. Dr. Luis Serrano, founder of Serrano Academy and author of the bestselling book Grokking Machine Learning, describes "word gravity": that is, how transformer architectures "bend space".
3. Dr. Caitlin Malone, host of the very popular Linear Digressions podcast, fills us in on how A.I. automations brought the show back to life after a five-year hiatus.
4. Dell Technologies' distinguished engineers Ishan S. and Tyler Cox explain why agentic A.I. burns through tokens at a rate that is catching companies out... and what we can do about it.
5. Dr. Dilani Kahawala — a Harvard physics PhD who spent a decade in product leadership at Etsy, Facebook and Atlassian — tells me she has had to throw almost all of that product experience away as she began developing Anna, her always-on A.I. assistant for families. She then walks us through the three problems that turn out to be hardest when your product has no user interface and never stops running.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Filtering by Tag: #datascience
How AI Brought a Podcast Back From the Dead, with Linear Digressions’ Katie Malone
Dr. Caitlin Malone's extremely popular "Linear Digressions" podcast went silent for five years. Then A.I. made it possible to bring it back... and to manage it like a team. Hear all about effective agent teams in today's excellent episode.
More on Katie:
• Hosts and produces "Linear Digressions", one of the world's most popular data-science podcasts. (It's excellent — check it out!)
• Senior Researcher at Moonlite AI.
• Previously Sr Director of the A.I. Innovation Lab at the Health Care Service Corporation, Sr Director of Data Science at Tempus Labs, and Director of Data Science at Civis Analytics.
• Has taught machine learning via Udacity and at the University of Chicago.
• Holds a PhD in experimental particle physics from Stanford University focused on working with CERN data.
In this episode, Katie explains:
• Why managing people and managing A.I. agents are the same skill in different clothing.
• Why A.I. could hollow out the expertise we need to catch its mistakes.
• A fascinating range of data paradoxes from Simpson’s to Benford’s.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
In Case You Missed It in August 2026
If you're in the Northern Hemisphere, summer is drawing to a close... but, ICYMI, today's episode highlights the best bits of the hot hot hot conversations that we had on my podcast in August:
1. In one of the technically richest conversations ever on the show, MongoDB's Field CTO of A.I., Pete Johnson, details the two common traits every company seeing ROI on A.I. investment have.
2. Gurobi Optimization's manager of decision-intelligence strategy Jerry Yurchisin returns to the show to explain where the division of labour between agents and mathematical solvers ought to fall.
3. Priyanka "The Cloud Girl" Vergadia (bestselling author, ex-Google, ex-Microsoft) walks us through how she structures Claude skills so that her output stops being slop.
4. dbt Labs founder and CEO Tristan Handy explains why the semantic layer matters more, not less, now that analytics agents are the ones asking the questions.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
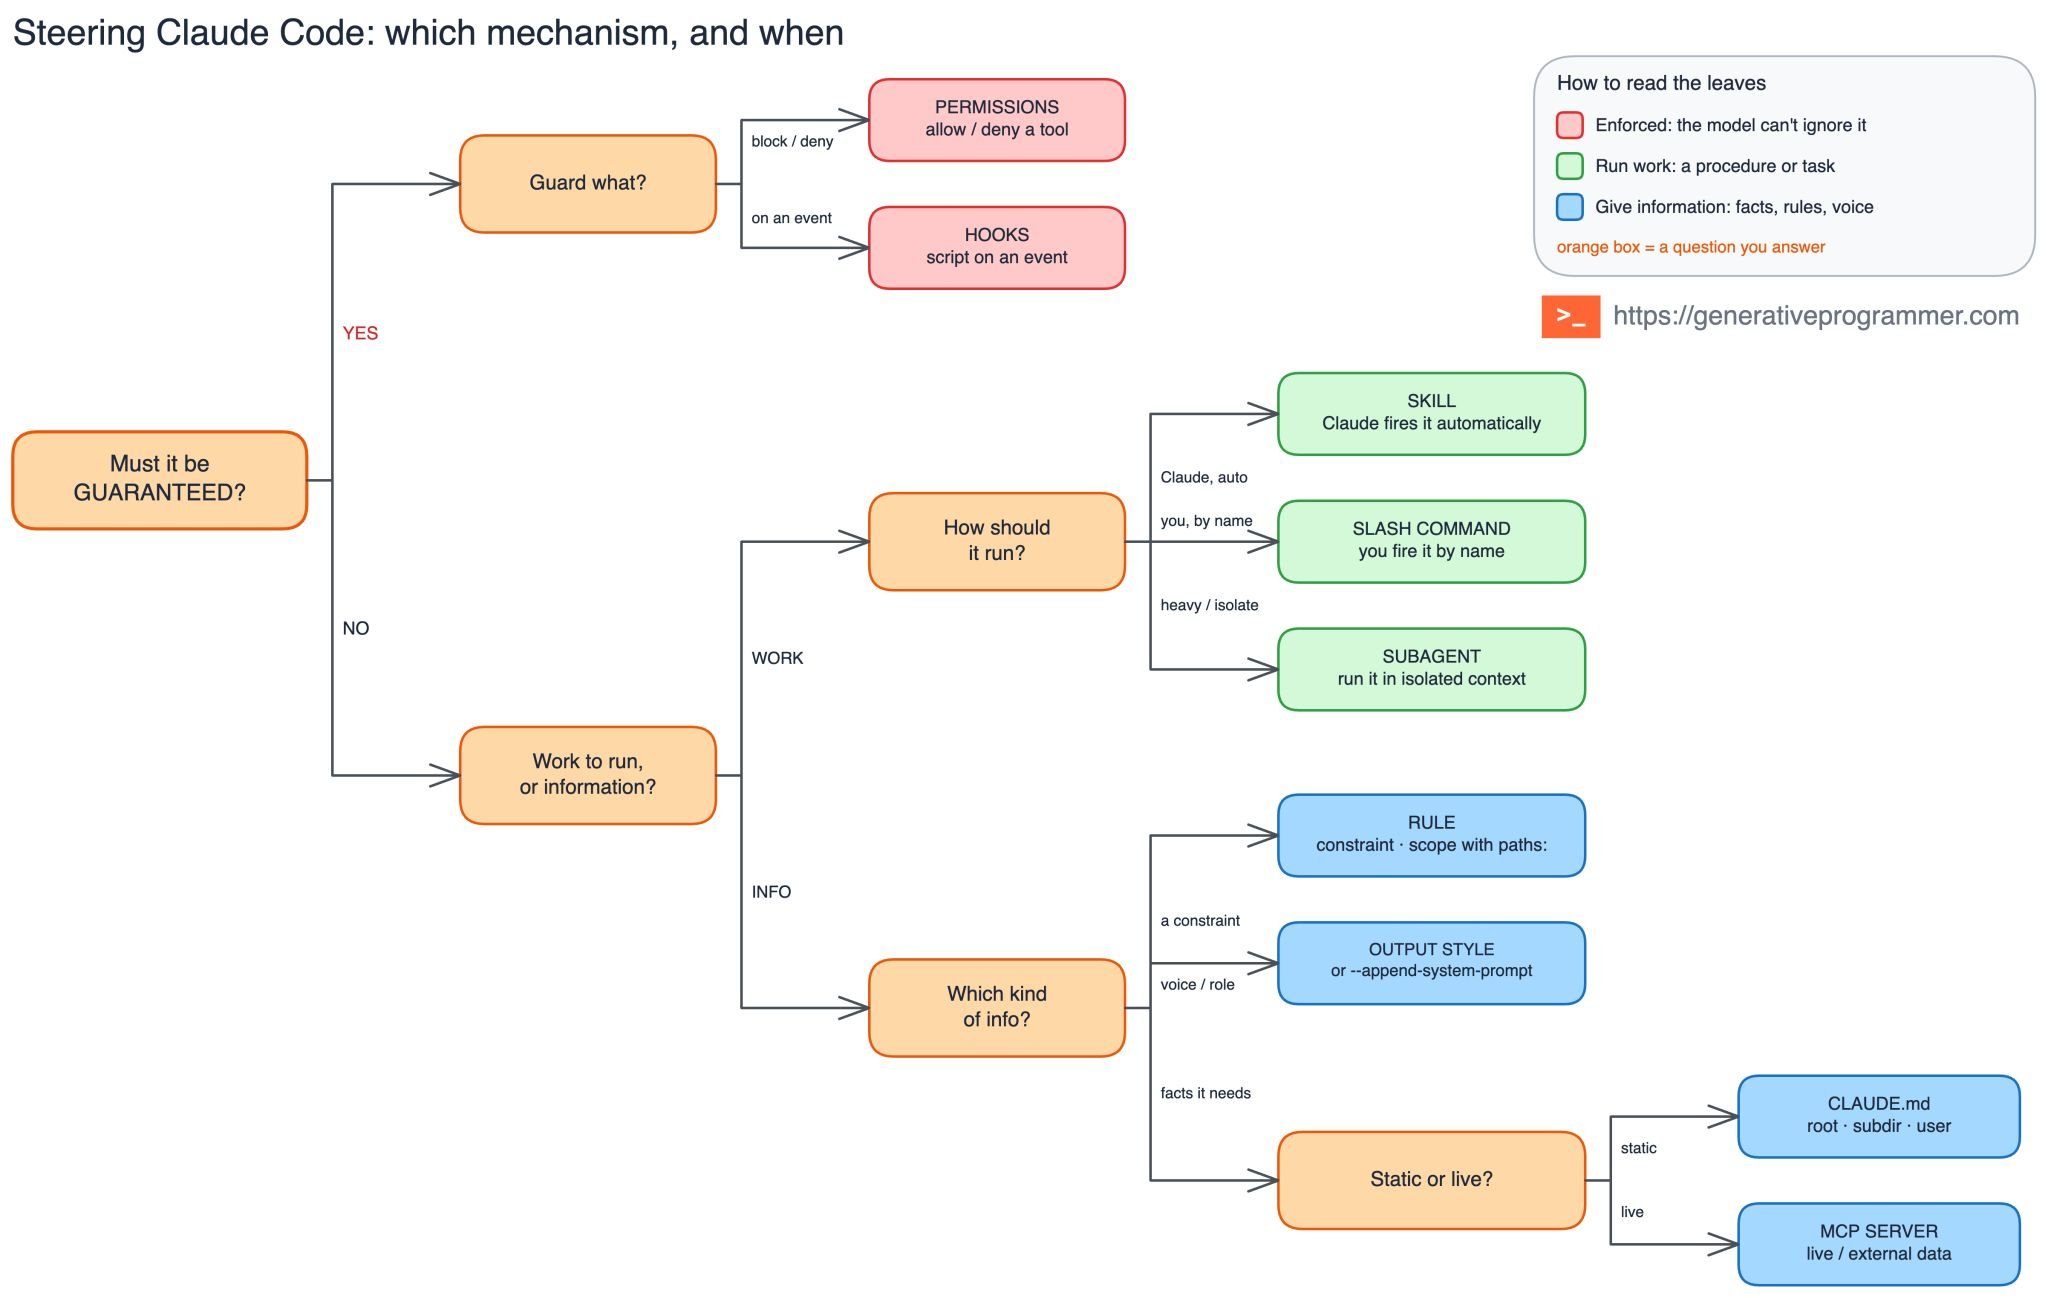
CLAUDE.md, AGENTS.md, Skills, Hooks and Subagents: A Field Guide to Steering AI Agents
Ever written careful instructions for an A.I. agent, only to watch it ignore them an hour into a session? The fix lies in knowing WHERE your instructions should live. Read on for all the details...
WHY AGENTS "FORGET"
• Everything an agent knows lives in its context window, and every token costs money and (more subtly) attention.
• Long sessions trigger "compaction": The conversation gets summarized to free up room, and instructions given early can get squeezed out.
• Every steering method answers one question: How do I make an instruction cheap to carry and hard for the agent to lose?
THE STEERING TOOLKIT (drawn from Anthropic's Claude Code, but the ideas generalize)
1.) Always-on files (e.g., CLAUDE.md): Loaded every session and re-read after compaction. Keep them under 200 lines, give them an owner, review changes like code.
2.) Rules: Path-scoped constraints that load only when relevant files are touched.
3.) Skills: Procedures (deploy workflows, checklists) whose full text loads only when invoked.
4.) Subagents: side tasks that run in isolated context windows... only the final summary returns.
5.) Hooks: deterministic code that fires on lifecycle events. The big idea: An instruction is a probability while a hook is a guarantee. If something must *never* happen, enforce it with code, not prose.
THE INDUSTRY IS CONVERGING
• AGENTS.md (kicked off by OpenAI, stewarded by the The Linux Foundation and backed by Google, Microsoft and AWS) serves similar function to CLAUDE.md and is read natively by Codex, Cursor, GitHub Copilot, Gemini CLI and dozens more tools across 60,000+ repositories.
• ETH Zurich researchers studied 138 real-world repos: Developer-written instruction files improved agent task success ~4% and cut agent-introduced bugs by 35-55%.
• The same study found LLM-generated instruction files DECREASED success while raising inference costs by 20%+. These data suggest the value is the human judgment encoded in the file... **you can't delegate the steering wheel to the thing being steered**.
NOT A CODER? THE SAME FRAMEWORK APPLIES
• Custom instructions = your always-on file (keep it short).
• Projects and Gems = your path-scoped rules.
• Custom GPTs = the consumer cousin of skills.
BOTTOM LINE
• Match persistence to relevance: always-on files stay ruthlessly short; procedures and area-specific conventions load on demand.
• "Always" and "never" are signals you need a guardrail (deterministic enforcement), not an instruction.
• Treat steering files as code: owned, reviewed and pruned. An instructions file that grows without gardening dilutes the instructions that matter.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
In Case You Missed It in July 2026
July featured some particularly striking conversations on my podcast with absolutely exceptional guests. ICYMI, today's episode highlights the best bits of my convos with them:
1. The mega-bestselling author of "Weapons of Math Destruction", Dr. Cathy O'Neil, makes the case that what makes an algorithm terrifying is not its complexity but other features entirely.
2. In his second appearance on the show, 80,000 Hours founder Benjamin Todd asks what happens if we do get a fully automated digital worker. We cover where solid ground is left for human careers, why the bottlenecks then move into the physical world, and how fast a robotics build-out could really go.
3. Blumberg Capital VC and five-time entrepreneur Steve Mock walks me through the patterns emerging from the stories he collects at aisavedme.org — chief among them that the people getting the most out of A.I. in healthcare are not asking it for advice, but using it to become far better-informed advocates for themselves.
4. Dr. Catherine Williams, Chief Data Officer at the nonprofit Candid, takes on a question I get asked all the time: does a deep understanding of the underlying mathematics still matter, now that large language models are getting so good at exactly the math and programming our field used to prize?
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
In Case You Missed It in June 2026
It is mighty hot in New York rn... but not nearly as spicy as the interviews on my podcast in June! ICYMI, here are the best bits of my on-air convos last month:
1. Two-time mega-bestselling O'Reilly author Chip Huyen on what's left for humans to do when the cost of building software is headed to $0.
2. Andrey Kurenkov, co-host of my favorite podcast ("Last Week in A.I.") and Founding A.I. Lead at Astrocade, on effective vibe-coding.
3. Lightning AI's VP of Infrastructure Frank Basso on what it's actually like inside an A.I. data center.
4. Gilbert Eijkelenboom on why 85% of data scientists can't communicate their work effectively... and the framework for fixing this.
5. In a role-reversal for landmark Episode #1001, the founder and original host of the SuperDataScience Podcast, Kirill Eremenko, interviewed me. In this clip, we discussed whether AGI would require something like consciousness to be realized.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
People Skills for Analytical Thinkers, with Bestselling Author Gilbert Eijkelenboom
Gilbert Eijkelenboom was a pro poker player who read his opponents through data alone but in today's episode, the bestselling author explains why the people side of data science matters more than the math.
More on Gilbert:
• Wrote the bestselling book "People Skills for Analytical Thinkers".
• Run MindSpeaking, a firm that's trained over 15,000 (mostly technical) folks on "people skills".
• Folks love his invaluable content, allowing him to gather over 200k followers.
• Was previously Managing Consultant on data and digital analytics for Capgemini, as well as a professional poker player on BetVictor.
• Holds a Master's in behavioral economics from Maastricht University.
In today's episode, Gilbert covers:
• Why no matter how good your model or analysis is, it only creates value once people actually use it, which makes communication a core data skill rather than an optional extra.
• His "and, but, therefore" communications framework.
• How research suggests only around 15% of people are self-aware and his tips for closing that gap.
• How experiences in childhood install personal "algorithms" in our adult behavior like avoiding conflict or staying silent... but we can change as adults (and he also provides tips on how).
Thanks to Kate Strachnyi for suggesting Gilbert as a guest!
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Ten Years of the Super Data Science Podcast, with Jon, Kirill and Special Guests
Today, we published Episode #1000 of the SuperDataScience Podcast! To celebrate, the show's original host Kirill Eremenko joined me and dozens of regular listeners on air to predict what the next 10 years of A.I. will bring.
In a bit more detail:
• We publish 104 episodes per year so Episode #1000 coincides with the show being about ten years old.
• The show was founded by Kirill Eremenko in 2016, who hosted over 400 episodes before handing me the reins in 2021.
• In a first for the show, Episode #1000 was streamed live online with our audience invited to join on air.
• Most folks interacted via chat functionality but a number of surprise guests came right onto the recording including Natalie Ziajski and Mario Pombo from the podcast team, rockstar A.I. entrepreneur Jepson Taylor, my 96-year-old grandmother and my very own pa, William Krohn.
• Kirill and I looked back on a decade of the podcast and fielded listener questions on topics such as A.I.’s biggest opportunities, the build-versus-buy dilemma, how to break into the field today, and how to stay grounded amid the relentless pace of A.I.
Thank you for support and listenership over all these years — we make this show for you and couldn't do it without you! We're excited to see what the next decade brings :)
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
In Case You Missed It in May 2026
Well, I certainly learned a lot from the outstanding guests we had on my podcast in May. ICYMI, today's episode features the best parts of my conversations with them:
1. Rubrik's Anneka Gupta and Cal Al-Dhubaib on how, in the Mythos era, the old cybersecurity playbook of prevention and detection is no longer enough, and how A.I. agents themselves are becoming a new source of data exposure inside organizations.
2. marimo's Dr. Trevor Manz on why code notebooks have become the natural working memory for A.I. coding agents. Trevor walks me through the Marimo Pair skill, which lets you drive a notebook from your agent, collaborating with Claude Code or Codex in real time as you load, explore, and visualize your data.
3. Jazmia Henry of collide. walks me through her work as a "full-stack" foundation model builder. We cover all four stages of the process: the often unglamorous slog of data curation, building bespoke tokenizers and embeddings, model training and reinforcement learning, and the inference layer that serves it all to end users.
4. Jacob Miller and Jeremy Mumford of Pattern (and authors of the great, brand-new book "Architected Intelligence") argue that the most expensive AI mistake an organization can make is failing slowly and sticking with prototypes long past their sell-by date because the traditional software mindset says you have to. We, of course, also discuss a solution.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Episode #1000: Join Us Live for the First-Ever Interactive SDS Podcast!
Ten years ago, Kirill Eremenko founded The SuperDataScience Podcast. To celebrate the upcoming Episode #1000, we are inviting you to join us both in a format we've never tried before:
It will be the first-ever interactive episode where you can join in online as we record, and ask your questions... or I suppose just make comments! You'll be able to ask share your thoughts in the chat or come right onto the show via video.
Kirill (founder, original host) and I (current host) will both be there, so you can ask us anything, e.g.:
• Did Kirill think the show would last ten years and 1000 episodes?
• How has data science transformed over the past decade?
• Did Jon have hair on his head ten years ago?
Date: Next Thursday, June 4th
Time: 5pm Eastern Time / 2pm Pacific Time
To get a calendar invite that includes the URL to join us live, check out the Luma link below ⬇️
luma.com/7vl7mdos
The "Super Data Science Podcast with Jon Krohn" is available on all major podcasting platforms and a video version is on YouTube. Whether you join us or not for the interactive recording, Episode #1000 will be published on Friday June 12th!
Pair Programming with AI in Your Python Notebook, with Dr. Trevor Manz
Exceptional technical episode today with Dr. Trevor Manz on "marimo Pair", an actually!) game-changing pair-programming A.I.-agent companion that lifts heavy loads within your Python data-science notebook.
More on Trevor:
• 27-time NCAA Swimming All-American & National Champion.
• Master's in Computational Biology from University of Cambridge.
• PhD in Bioinformatics from Harvard University.
• Creator of the popular open-source "anywidget" project (amongst many others, particularly in visualizing bioinformatics data, e.g., genomics data).
• Now a founding engineer at marimo.io, where he is leading the charge on marimo Pair.
Seriously, marimo Pair is unreal. A complete reimagining of what's possible in a Jupyter notebook-style environment in the agentic A.I. era. You will hear (and see) my mind explode in this episode!
We also discuss:
• Agent skills.
• Recursive language models.
• A number of other open-source projects, largely in data viz/analysis.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.