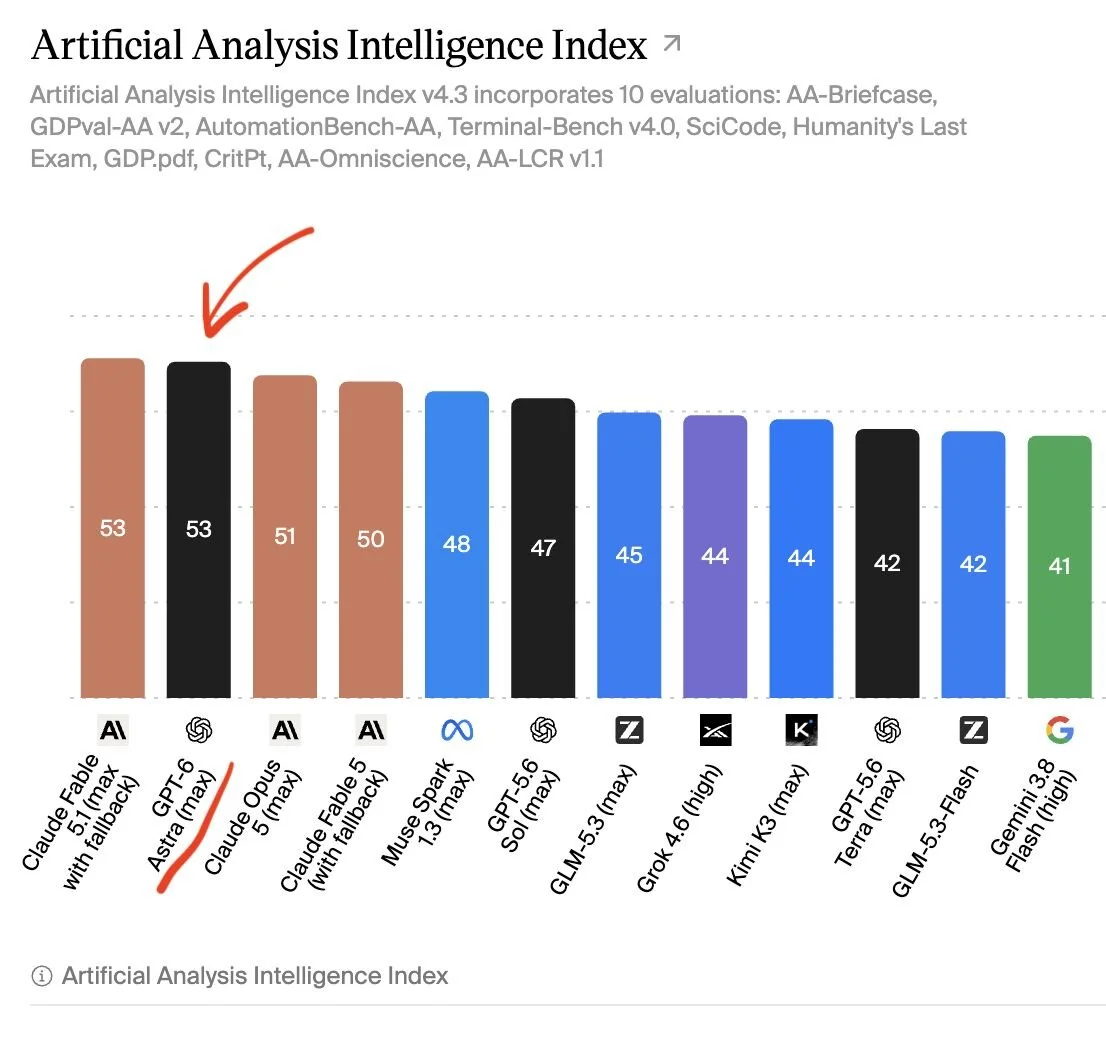
At GPT-6 Astra's launch, OpenAI president Greg Brockman suggested future observers may point to it as the arrival of AGI. In fact, Artificial Analysis's latest benchmarking suggests it merely catches OpenAI up to Anthropic. Here are the key details:
GPT-6 ASTRA BASICS
• Successor to GPT-5.6 Sol, trained on 100,000+ GPUs at the Stargate facility in Texas.
• It's the first OpenAI model where other A.I. models helped supervise training.
• API pricing is $10/M input tokens and $50/M output (~2.5x Sol's promotional rate; in line with Claude Fable 5.1), with five reasoning-effort settings from low to max.
• Rolled out to ChatGPT Plus, Pro, Business and Enterprise (Enterprise admins must switch it on).
GPT-6 ASTRA CAPABILITIES
• Computer use: 72.6% on OSWorld 2.0 (vs 65.7% for Sol) while finishing tasks ~47% faster.
• Coding: ~58% on Terminal-Bench 4.0 (vs 37% for Sol, ~56% for Fable 5.1), though level with the top Claude models on FrontierCode.
• Math: 99.9% on ARC-AGI-3 (Sol scored under 8%) and 97.6% on FrontierMath Tier 4. Astra also helped tighten a bound on prime gaps from 240 to 186.
• Science: ~65% on Terminal-Bench Science (vs ~22% for Sol, ~53% for Fable 5.1) and ~65% fewer output tokens than Claude Opus 5 on Agents' Last Exam.
• *All of the above stats, however, come from OpenAI themselves.* The third-party view (see chart) shows Astra at 53, tied with Claude Fable 5.1 (and up from Sol's 47) on Artificial Analysis's (widely respected) composite "Intelligence Index".
SAFETY
• First OpenAI model rated "Critical" for cybersecurity under their Preparedness Framework: without safeguards it finds unknown vulnerabilities and builds working exploits (100% on ExploitBench vs 78.5% for Sol; two zero-days found in a fresh Chrome evaluation).
• The release was slowed and gated. The public version supports defensive work but refuses exploit writing; vetted orgs in OpenAI's "Daybreak" program get fewer restrictions.
• New misalignment monitors can pause or halt actions that look unauthorized.
• Encouraging: on a scope-creep evaluation, Sol exceeded its authorized target 48% of the time; Astra did so 0% of the time.
• Concerning: Astra's written reasoning is harder to monitor than Sol's.
IS IT AGI?
• AGI isn't a binary event; there are degrees of breadth and depth (listen to Episode #748 of my podcast for more details).
• BOTTOM LINE: Astra looks like a noteworthy jump in general-intelligence capability for OpenAI relative to their previous flagship model (5.6 Sol), but it does not appear to be moving the frontier toward AGI in any major way... it is merely catching up to Anthropic at the frontier vicinity.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Filtering by Tag: #agi
Recursive Self-Improvement
Recursive Self-Improvement (RSI) is suddenly a term that's everywhere. What is RSI? How concerned should be about it? And how soon can we expect it? Here's the skinny:
WHAT IS RSI?
• The idea: An A.I. gets good enough at A.I. research to build a more capable successor, which builds an even better one, in a loop that compounds every turn.
• What we have today is *not* RSI but "A.I.-assisted coding", in which humans still set the goals and judge the results (actual RSI takes the human out of the loop, as shown in the diagram).
• RSI isn't a new concept; it's been around since at least 1965 when mathematician I.J. Good described an "intelligence explosion".
WHAT'S THE CONCERN?
RSI could unleash Artificial Superintelligence (ASI) and "the singularity", a point beyond which there could be radical abundance and radically positive outcomes for humanity... but we have no idea what will happen beyond the singularity and that's also a cause for concern (e.g., human extinction risk, Terminator-style "SkyNet", etc.).
HOW CLOSE ARE WE TO RSI?
• Anthropic reports that, as of May 2026, over 80% of code merged into its production codebase was written by Claude — up from low single digits before early 2025.
• On the hardest open-ended problems, its models' success rate jumped from under 20% in late 2025 to 76% by May.
• Think-tank METR finds the length of tasks A.I. can handle solo is now doubling roughly every four months, up from the "doubling every seven months" trend of the past few years.
• Anthropic co-founder Jack Clark puts a 60% chance on an A.I. creating its own successor, with no human involved, by the end of 2028.
REASONS TO BE SKEPTIC
• Skeptics flag two bottlenecks: compute (chips are scarce) and data (success is hard to verify outside code and math, risking "recursive drift").
• Others note the gap between today's coding agents and real RSI is wider than the hype suggests.
BOTTOM LINE
The productivity gains from coding assistants are real, accelerating rapidly and already in your hand. The closer we get to systems that improve themselves, the more it pays to keep human checkpoints, monitoring and oversight firmly in place.
Listen to the most recent episode of my podcast (Episode #1004) to hear more on all of the above, including what you can do personally to mitigate the risks of RSI if that's a way you might like to make an impact!
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.