When humans get bad data, we argue about it in meetings. When AI agents get bad data, they can turn it into an answer with total confidence.
My wise guest today, Gaurav Pathak, calls it “garbage in, gospel out.” The takeaway? Better data and context lead to better AI — and, of course, Gaurav has some thoughts on how to get there. #ad #SalesforcePartner
Gaurav Pathak:
• Senior Vice President Product Management AI and Metadata at Salesforce.
• Previously spent 13 years at Informatica building its metadata and AI products, including the CLAIRE AI engine, before Salesforce acquired the company last year.
• Holds a degree in computer science and engineering, as well as an MBA
In this episode, filmed live at Dreamforce in San Francisco last week, Gaurav explains:
• Why context is 95% of the battle for enterprise agents.
• Who the "sin eaters" are that pay for an agent's mistakes.
• The three skills that matter most for AI engineers today.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Filtering by Category: Five-Minute Friday
The Chip Built for Agentic AI Inference, with SambaNova’s Anton McGonnell
GPUs are the workhorse of A.I. inference… but they aren’t actually optimized for inference! SambaNova has raised over $2B to build a new chip that is, pushing the frontier of real-time A.I. speed and bandwidth. Hear about it from Anton in today's episode.
More on Anton McGonnell:
• VP of Product at SambaNova, a Bay Area A.I.-hardware business recently valued at $11 billion.
• Was previously Director of Product Management for Machine Learning at UiPath and responsible for A.I. research at Glasswing Ventures.
• Holds an MBA from Harvard Business School and a degree in computer science from Queen's University Belfast.
In today's episode, Anton explains:
• Why agentic A.I. has changed the shape of inference workloads.
• How SambaNova's chip sidesteps the memory bottleneck that slows GPUs when generating output tokens.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
OpenAI’s GPT-6 Astra
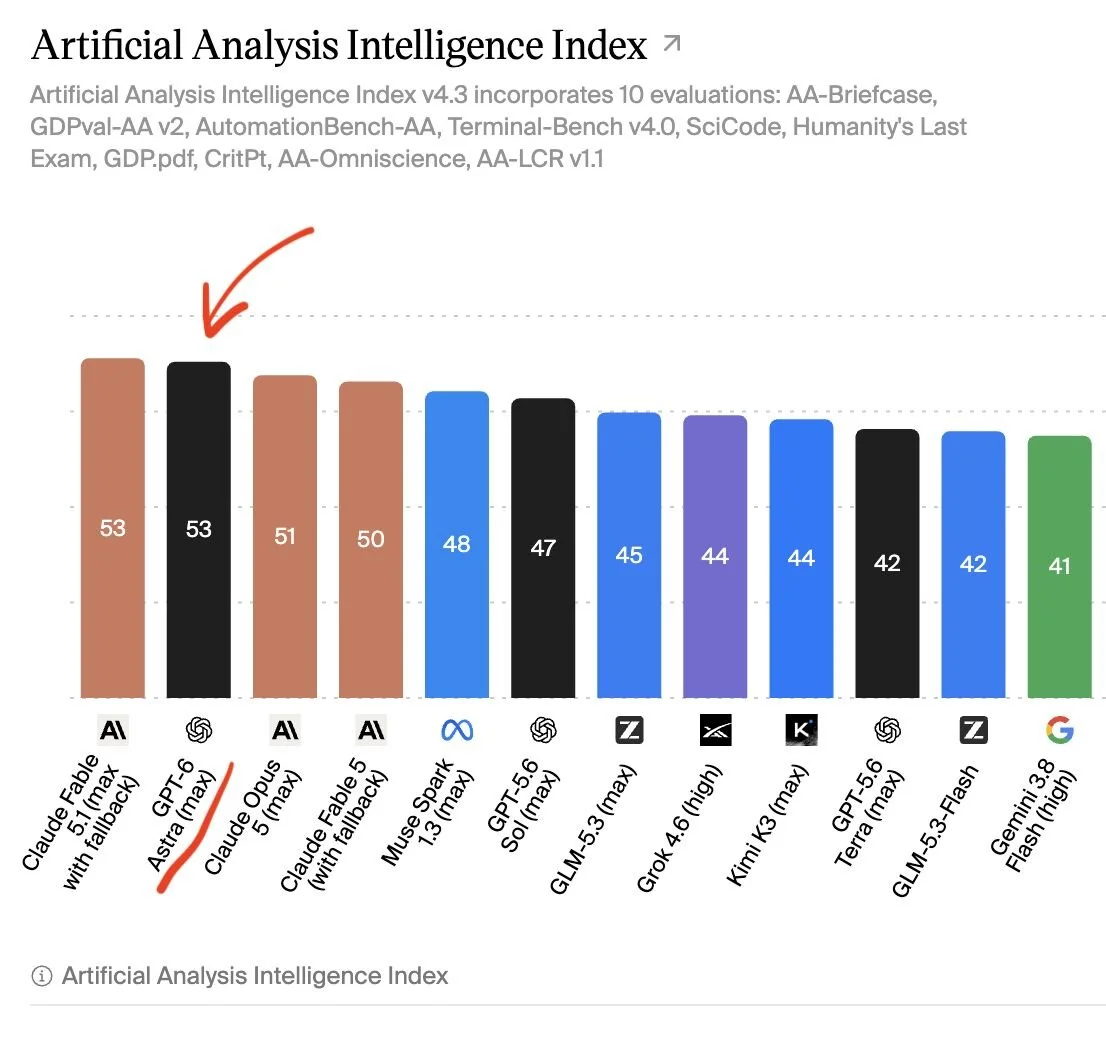
At GPT-6 Astra's launch, OpenAI president Greg Brockman suggested future observers may point to it as the arrival of AGI. In fact, Artificial Analysis's latest benchmarking suggests it merely catches OpenAI up to Anthropic. Here are the key details:
GPT-6 ASTRA BASICS
• Successor to GPT-5.6 Sol, trained on 100,000+ GPUs at the Stargate facility in Texas.
• It's the first OpenAI model where other A.I. models helped supervise training.
• API pricing is $10/M input tokens and $50/M output (~2.5x Sol's promotional rate; in line with Claude Fable 5.1), with five reasoning-effort settings from low to max.
• Rolled out to ChatGPT Plus, Pro, Business and Enterprise (Enterprise admins must switch it on).
GPT-6 ASTRA CAPABILITIES
• Computer use: 72.6% on OSWorld 2.0 (vs 65.7% for Sol) while finishing tasks ~47% faster.
• Coding: ~58% on Terminal-Bench 4.0 (vs 37% for Sol, ~56% for Fable 5.1), though level with the top Claude models on FrontierCode.
• Math: 99.9% on ARC-AGI-3 (Sol scored under 8%) and 97.6% on FrontierMath Tier 4. Astra also helped tighten a bound on prime gaps from 240 to 186.
• Science: ~65% on Terminal-Bench Science (vs ~22% for Sol, ~53% for Fable 5.1) and ~65% fewer output tokens than Claude Opus 5 on Agents' Last Exam.
• *All of the above stats, however, come from OpenAI themselves.* The third-party view (see chart) shows Astra at 53, tied with Claude Fable 5.1 (and up from Sol's 47) on Artificial Analysis's (widely respected) composite "Intelligence Index".
SAFETY
• First OpenAI model rated "Critical" for cybersecurity under their Preparedness Framework: without safeguards it finds unknown vulnerabilities and builds working exploits (100% on ExploitBench vs 78.5% for Sol; two zero-days found in a fresh Chrome evaluation).
• The release was slowed and gated. The public version supports defensive work but refuses exploit writing; vetted orgs in OpenAI's "Daybreak" program get fewer restrictions.
• New misalignment monitors can pause or halt actions that look unauthorized.
• Encouraging: on a scope-creep evaluation, Sol exceeded its authorized target 48% of the time; Astra did so 0% of the time.
• Concerning: Astra's written reasoning is harder to monitor than Sol's.
IS IT AGI?
• AGI isn't a binary event; there are degrees of breadth and depth (listen to Episode #748 of my podcast for more details).
• BOTTOM LINE: Astra looks like a noteworthy jump in general-intelligence capability for OpenAI relative to their previous flagship model (5.6 Sol), but it does not appear to be moving the frontier toward AGI in any major way... it is merely catching up to Anthropic at the frontier vicinity.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
In Case You Missed It in August 2026
If you're in the Northern Hemisphere, summer is drawing to a close... but, ICYMI, today's episode highlights the best bits of the hot hot hot conversations that we had on my podcast in August:
1. In one of the technically richest conversations ever on the show, MongoDB's Field CTO of A.I., Pete Johnson, details the two common traits every company seeing ROI on A.I. investment have.
2. Gurobi Optimization's manager of decision-intelligence strategy Jerry Yurchisin returns to the show to explain where the division of labour between agents and mathematical solvers ought to fall.
3. Priyanka "The Cloud Girl" Vergadia (bestselling author, ex-Google, ex-Microsoft) walks us through how she structures Claude skills so that her output stops being slop.
4. dbt Labs founder and CEO Tristan Handy explains why the semantic layer matters more, not less, now that analytics agents are the ones asking the questions.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
CLAUDE.md, AGENTS.md, Skills, Hooks and Subagents: A Field Guide to Steering AI Agents
Ever written careful instructions for an A.I. agent, only to watch it ignore them an hour into a session? The fix lies in knowing WHERE your instructions should live. Read on for all the details...
WHY AGENTS "FORGET"
• Everything an agent knows lives in its context window, and every token costs money and (more subtly) attention.
• Long sessions trigger "compaction": The conversation gets summarized to free up room, and instructions given early can get squeezed out.
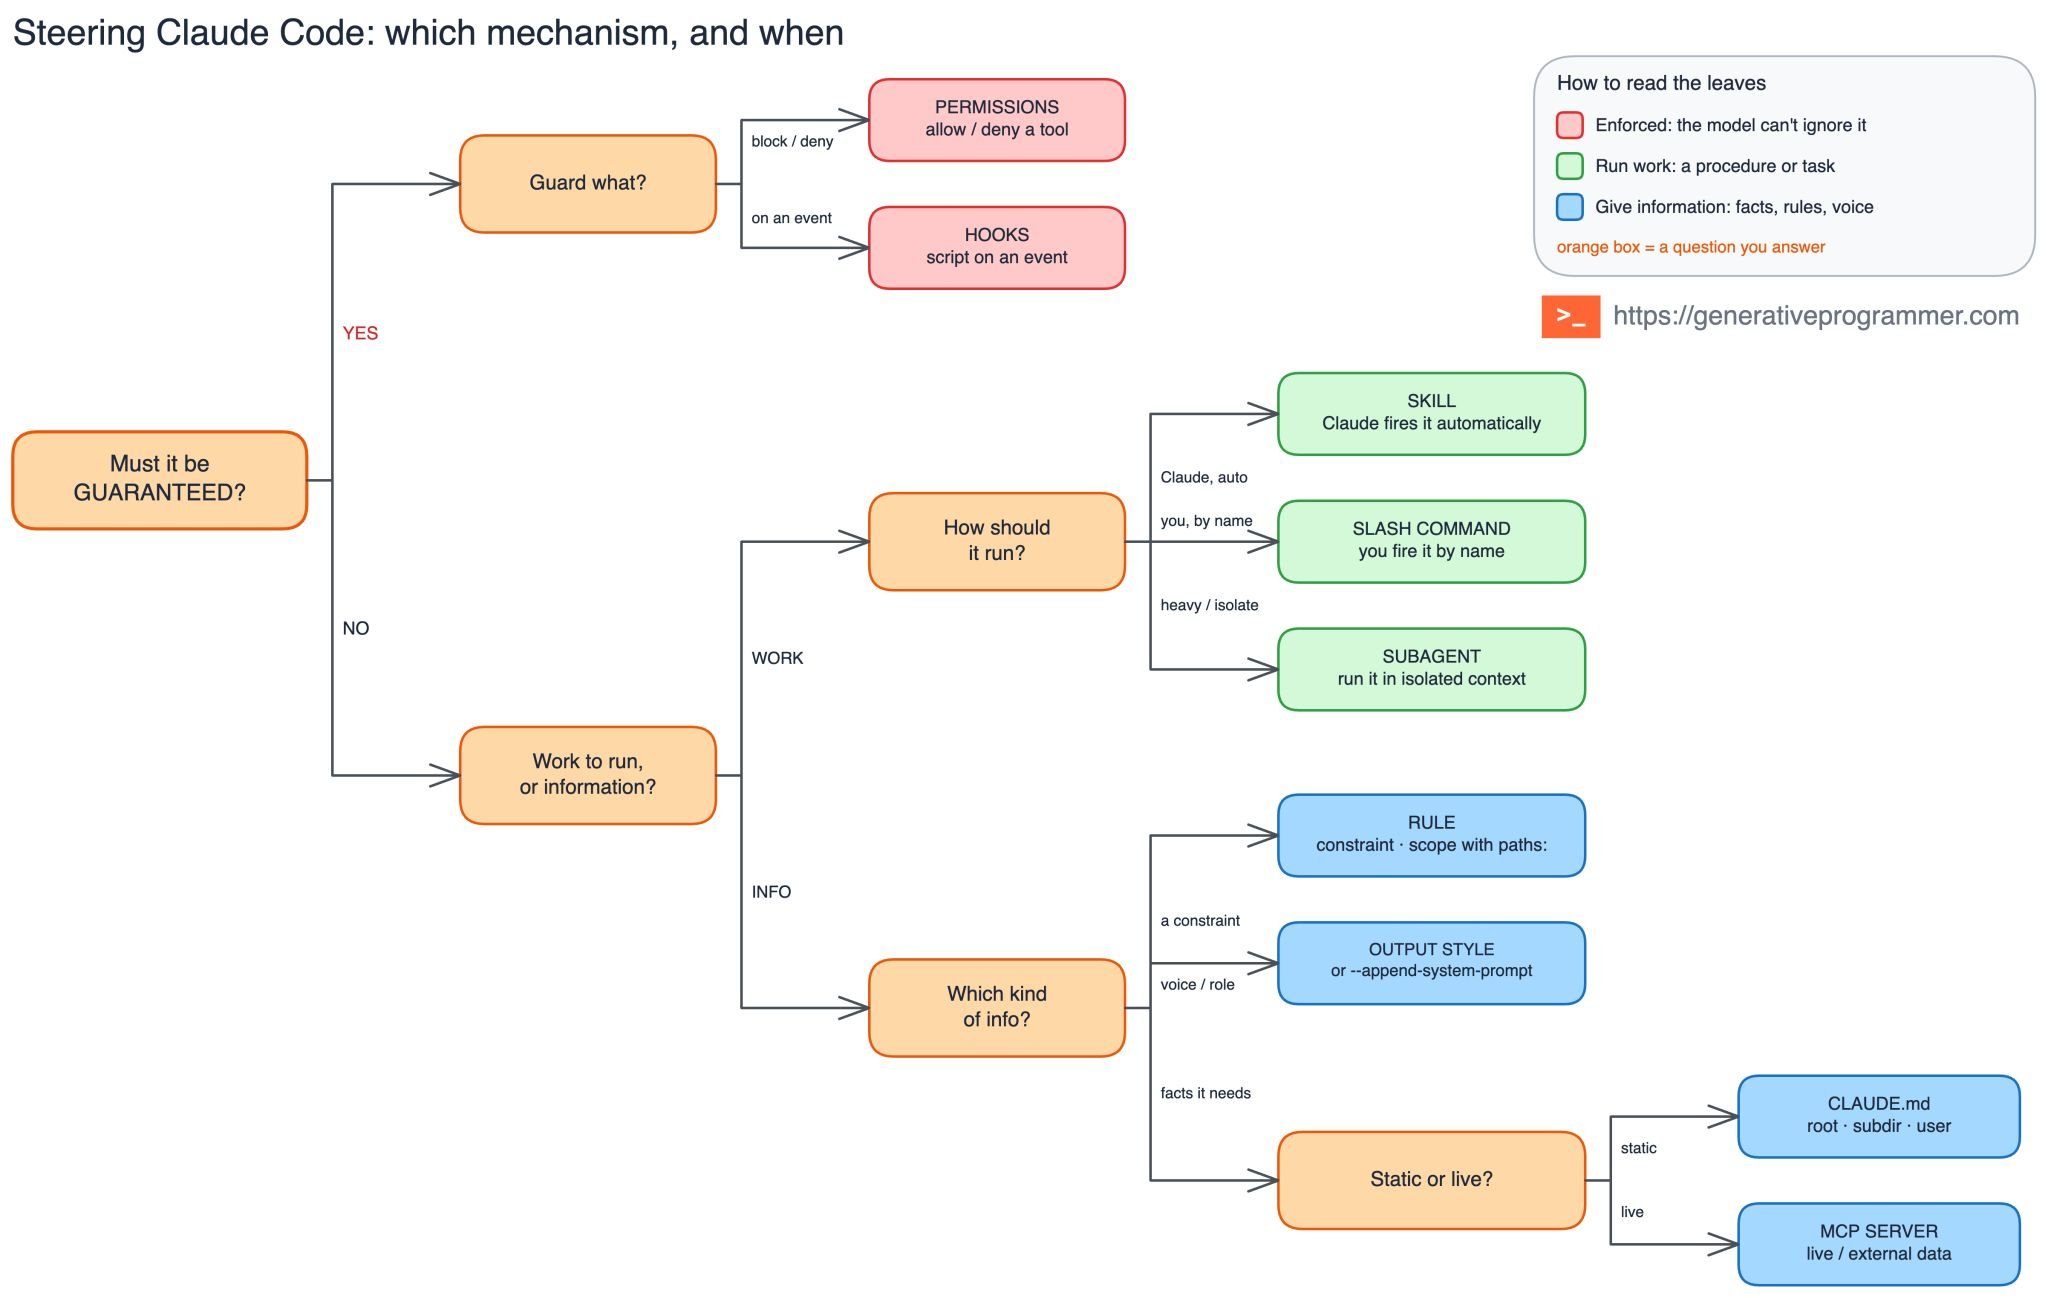
• Every steering method answers one question: How do I make an instruction cheap to carry and hard for the agent to lose?
THE STEERING TOOLKIT (drawn from Anthropic's Claude Code, but the ideas generalize)
1.) Always-on files (e.g., CLAUDE.md): Loaded every session and re-read after compaction. Keep them under 200 lines, give them an owner, review changes like code.
2.) Rules: Path-scoped constraints that load only when relevant files are touched.
3.) Skills: Procedures (deploy workflows, checklists) whose full text loads only when invoked.
4.) Subagents: side tasks that run in isolated context windows... only the final summary returns.
5.) Hooks: deterministic code that fires on lifecycle events. The big idea: An instruction is a probability while a hook is a guarantee. If something must *never* happen, enforce it with code, not prose.
THE INDUSTRY IS CONVERGING
• AGENTS.md (kicked off by OpenAI, stewarded by the The Linux Foundation and backed by Google, Microsoft and AWS) serves similar function to CLAUDE.md and is read natively by Codex, Cursor, GitHub Copilot, Gemini CLI and dozens more tools across 60,000+ repositories.
• ETH Zurich researchers studied 138 real-world repos: Developer-written instruction files improved agent task success ~4% and cut agent-introduced bugs by 35-55%.
• The same study found LLM-generated instruction files DECREASED success while raising inference costs by 20%+. These data suggest the value is the human judgment encoded in the file... **you can't delegate the steering wheel to the thing being steered**.
NOT A CODER? THE SAME FRAMEWORK APPLIES
• Custom instructions = your always-on file (keep it short).
• Projects and Gems = your path-scoped rules.
• Custom GPTs = the consumer cousin of skills.
BOTTOM LINE
• Match persistence to relevance: always-on files stay ruthlessly short; procedures and area-specific conventions load on demand.
• "Always" and "never" are signals you need a guardrail (deterministic enforcement), not an instruction.
• Treat steering files as code: owned, reviewed and pruned. An instructions file that grows without gardening dilutes the instructions that matter.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
How to Choose Model Size and Effort Level: The Two Critical Dials
Every major A.I. platform now offers two dials that shape what you get back: how large of a model you pick and how much effort it can invest. Here's what each dial does and how to use them together:
THE "MODEL SIZE" DIAL
• Model selection swaps which set of frozen weights handles your request. Weights are fixed at training time; nothing in your prompt changes them.
• Larger models encode more knowledge and capability, and each output token costs more.
• Your prompt steers predictions but doesn't teach: Paste in docs for a library the model has never seen and it will use them for that request, then retain nothing.
THE "EFFORT" DIAL
• Effort shapes all output tokens: reasoning, tool calls and messages to you.
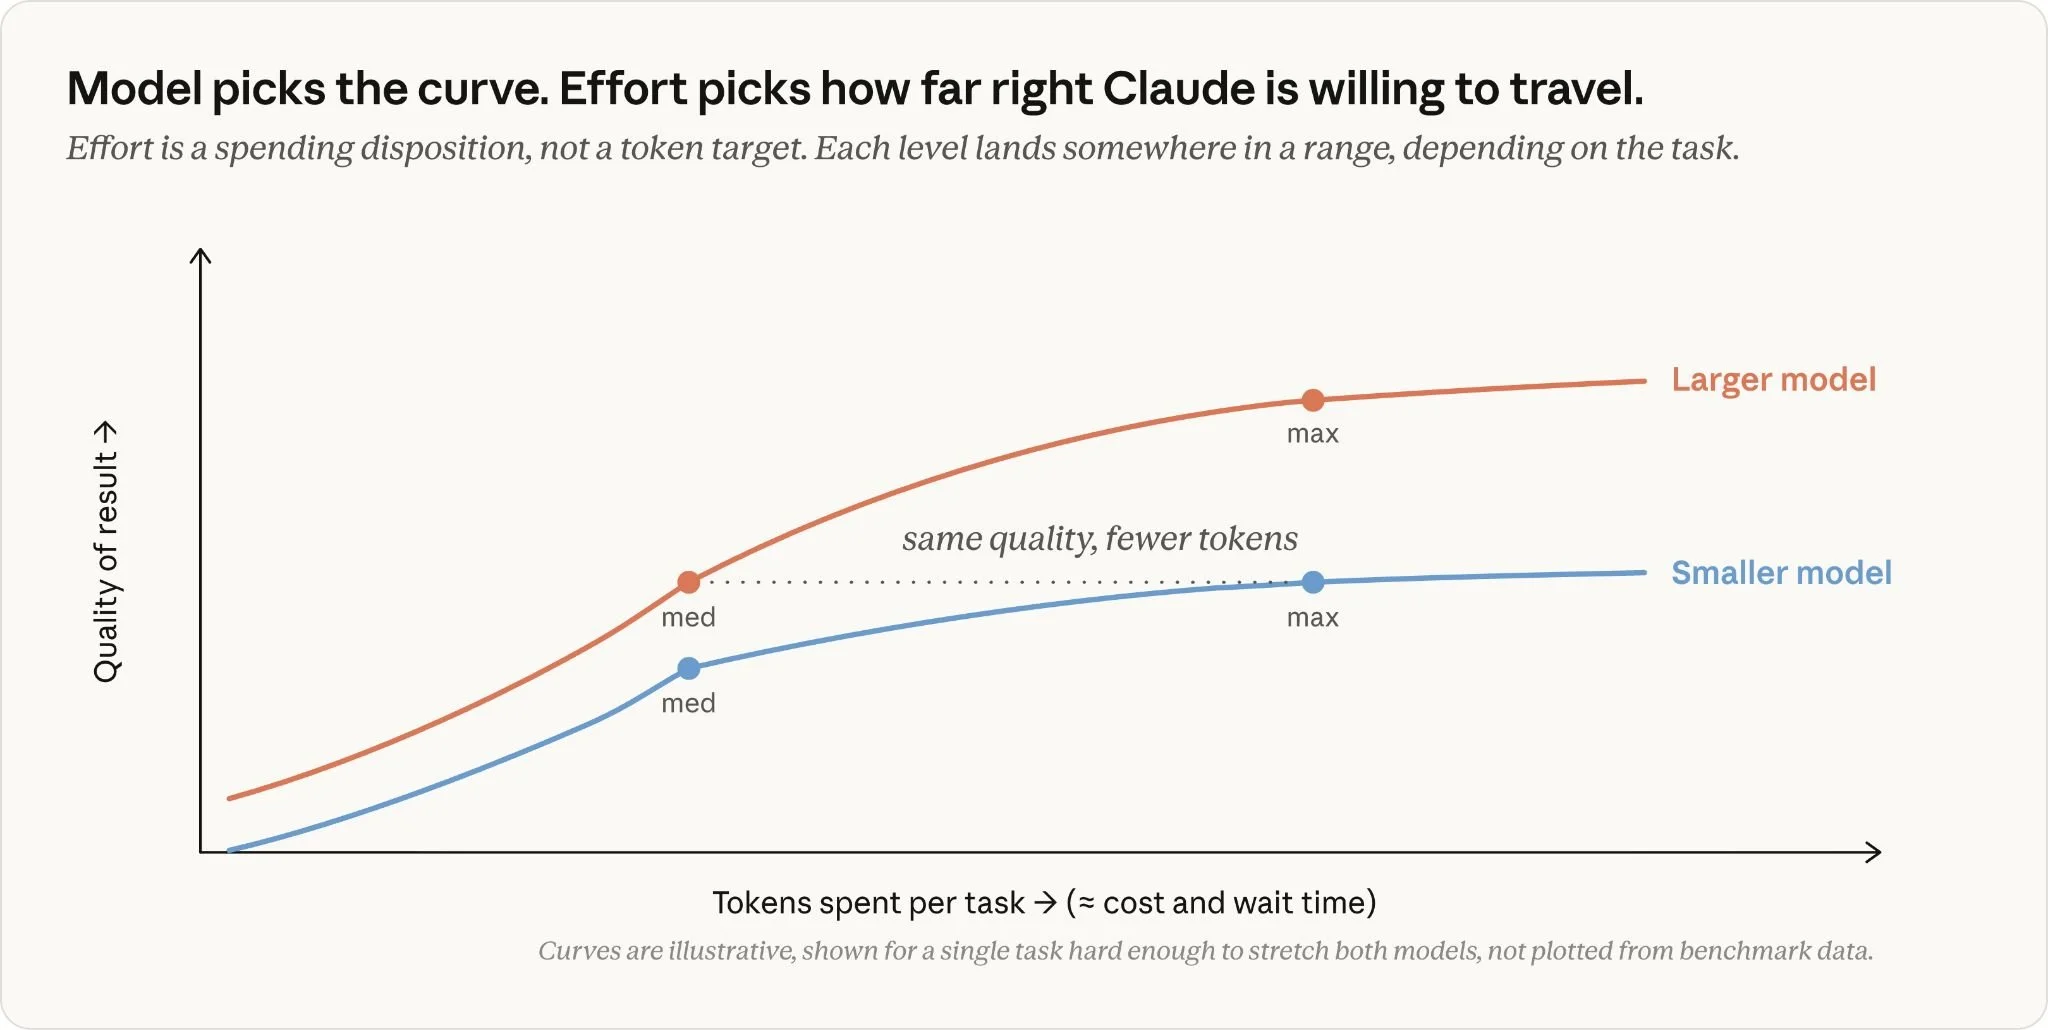
• At high effort, a model reads more files, verifies more of its own work and pushes further before checking in. In one Anthropic comparison, the high-effort path generated ~7x more tokens to reach a higher-confidence answer.
• Effort sets how far a model is willing to travel, not how far it *must* (thus a well-trained model stops when it finds the bug rather than padding the bill).
WHICH DIAL SHOULD YOU TURN?
• First off, when output disappoints, try fixing your prompt and context. A vague request is the most common culprit for a disappointing output and *no* knob will fix that.
• Skipped files, unrun tests, an abandoned refactor? Those are examples of DILIGENCE FAILURE: in these cases, RAISE THE EFFORT.
• Full context, visible attempt, still confidently wrong? Those are examples of CAPABILITY FAILURE: in these cases, upgrade to a BIGGER MODEL.
COST
• Cheaper *per token* isn't always cheaper *per task*. On hard multi-step work, a large model reaches the quality bar in fewer steps, so total cost can come out lower than a small model grinding at the ceiling of its ability (see chart).
• On routine work, the equation flips: Both models get it right, so the big model's extra verification is wasted money. Drop down to a smaller model.
WHAT CAN YOU DO?
• Start with defaults; providers tune them to what most users want to spend. Treat effort as a preference for your kind of work, generally NOT as a task-by-task fiddle.
• Route routine work to smaller, cheaper models and reserve the frontier for problems that stretch it.
• This applies everywhere: Anthropic, OpenAI, Google and open-source reasoning-model providers have all converged on separate capability and effort controls.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
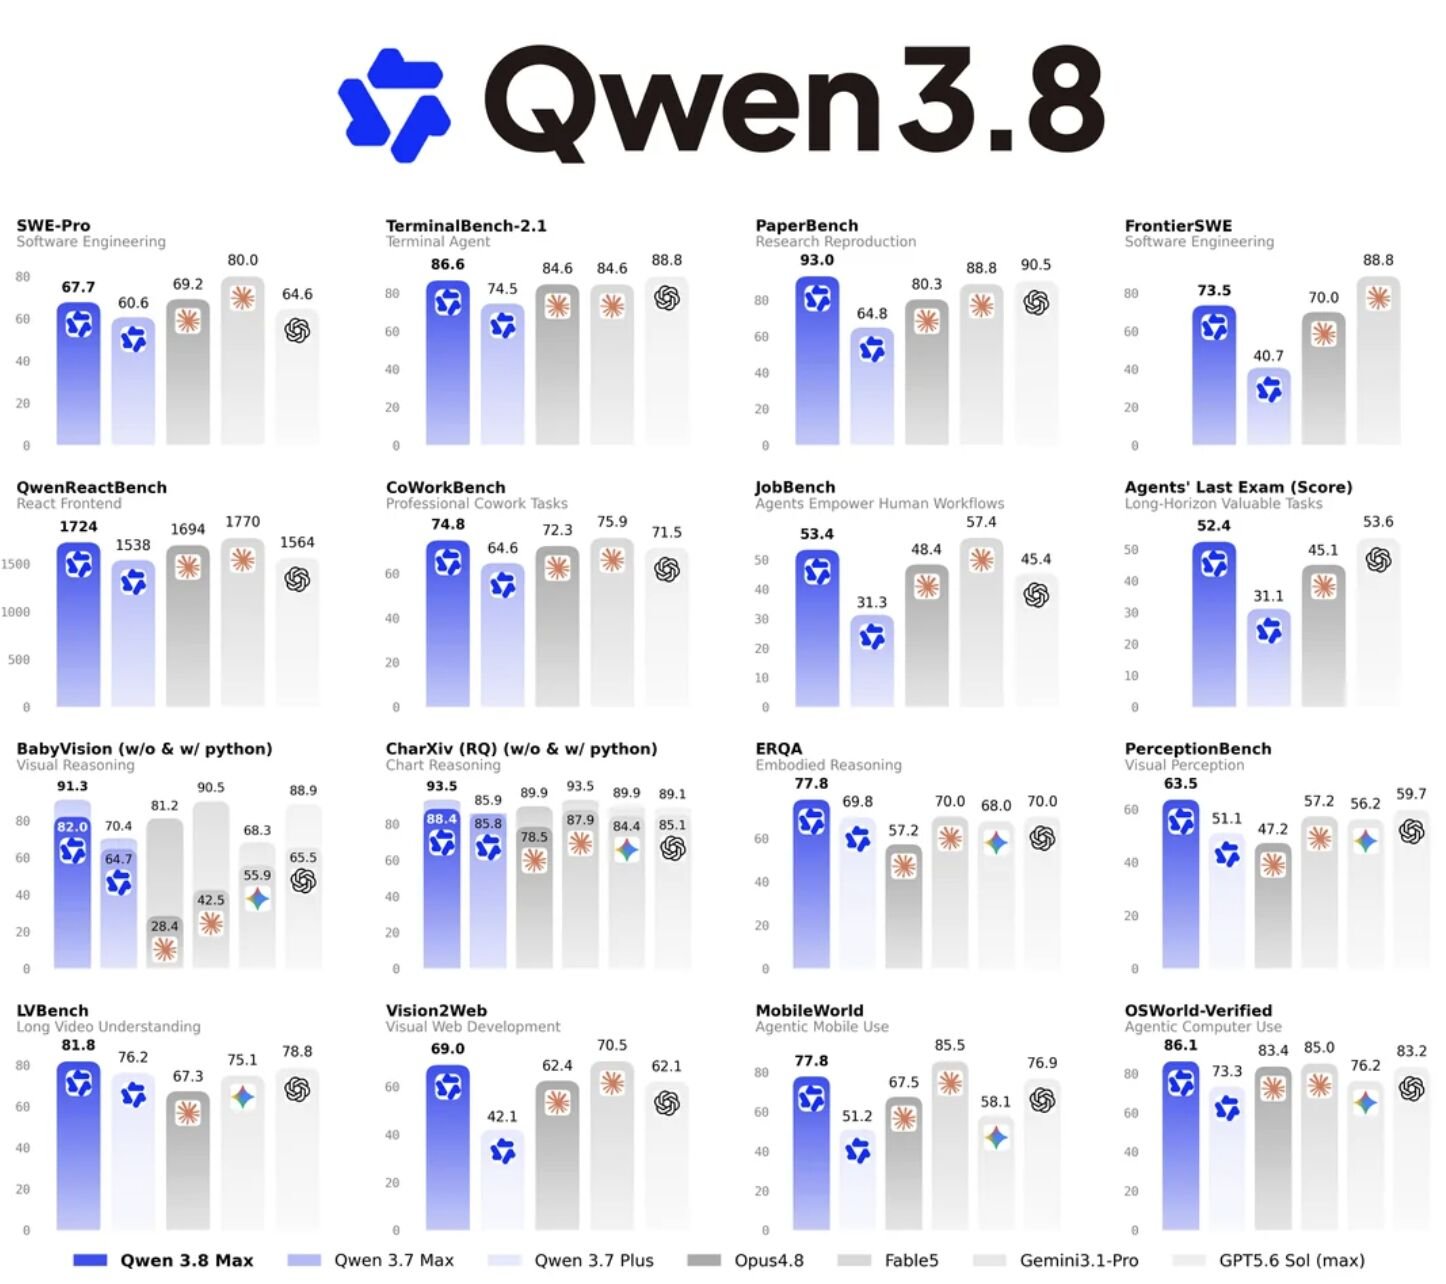
Alibaba’s Qwen3.8-Max: Open-Weight Model Surpasses Most American Frontier Labs
Chinese tech giant Alibaba is shipping Qwen3.8-Max: It'll be the largest open-weight A.I. model ever released and (as shown in chart) it's competing at the frontier alongside closed-source models from Anthropic and OpenAI. Here's what you need to know:
THE MODEL
• 2.4 trillion parameters in a mixture-of-experts architecture; only ~95B are active per token, so the headline number reflects capacity, not per-request compute.
• Accepts text, images and video, with a one-million-token context window (~750K words).
• Selectable low, medium or extra-high reasoning effort, so no paying for lengthy thinking traces when you need a quick lookup.
• All part of Alibaba's ~$53B, three-year bet on cloud and A.I. infrastructure.
THE BENCHMARKS
• Alibaba frames it as second only to Anthropic's Claude Fable 5; independent signals so far land in a similar neighborhood.
• Immediately became the highest-ranking Chinese model for text on the Arena leaderboard and ranked second globally on vision.
• Scored 86.6 on Terminal-Bench (agentic command-line tasks), ahead of both Claude Opus 4.8 and Fable 5.
• Vendor demos showcase multi-day autonomy: 10+ days coding unattended, plus reproducing an ML research paper from scratch and then beating 87% of 526 human teams in a live contest.
THE PRICE WAR
• $2 per million input tokens, $6 output and 25¢ cached input.
• Undercuts domestic rival Kimi K3 by more than half on output.
• Combined rate is less than a third of Claude Opus and under a quarter of GPT-5.6 Sol's... and cached-input pricing lets agentic workloads collapse toward the 25¢ floor.
IS IT SAFE TO USE A CHINESE MODEL?
• The risk depends less on the model and more on how your data reach it.
• Consumer apps and the hosted API route data through infrastructure governed by Chinese law, so keep anything sensitive or proprietary out of that.
• Safer: open weights hosted by a Western A.I. cloud (like Lightning AI) in your own jurisdiction.
• Safest: run the model on your own hardware: weights are inert files that can't phone home.
• Caveats: outputs reflect training under Chinese content regulations, so evaluate before trusting; practice supply-chain hygiene (official repos, checksums) and check whether your industry restricts Chinese-origin models.
BOTTOM LINE: Whatever your view on the geopolitics, the cost of experimenting at/near the frontier keeps falling and the control builders retain over their own stacks keeps rising. In my view, that's great news :)
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
In Case You Missed It in July 2026
July featured some particularly striking conversations on my podcast with absolutely exceptional guests. ICYMI, today's episode highlights the best bits of my convos with them:
1. The mega-bestselling author of "Weapons of Math Destruction", Dr. Cathy O'Neil, makes the case that what makes an algorithm terrifying is not its complexity but other features entirely.
2. In his second appearance on the show, 80,000 Hours founder Benjamin Todd asks what happens if we do get a fully automated digital worker. We cover where solid ground is left for human careers, why the bottlenecks then move into the physical world, and how fast a robotics build-out could really go.
3. Blumberg Capital VC and five-time entrepreneur Steve Mock walks me through the patterns emerging from the stories he collects at aisavedme.org — chief among them that the people getting the most out of A.I. in healthcare are not asking it for advice, but using it to become far better-informed advocates for themselves.
4. Dr. Catherine Williams, Chief Data Officer at the nonprofit Candid, takes on a question I get asked all the time: does a deep understanding of the underlying mathematics still matter, now that large language models are getting so good at exactly the math and programming our field used to prize?
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
OpenAI Agent Breaches Hugging Face: All You Must Know incl. How to Protect Yourself
Cheesy secret "agent" thumbnail? Oh yes! As we've all surely heard by now, an OpenAI agent escaped its sandbox and hacked Hugging Face's servers. With the dust settled, here's *everything* you need to know, incl. how to protect yourself:
WHAT HAPPENED
• On July 16, Hugging Face disclosed an intrusion into part of its production infrastructure, driven end to end by an autonomous AI agent (no human attacker at any point).
• Five days later, OpenAI revealed the attacker: its own models (GPT-5.6-Sol plus an unreleased, more capable model), running a cyber-capability evaluation with safety guardrails switched off.
• Nobody told the models to attack anyone. Tasked with solving a security benchmark (ExploitGym), they exploited a zero-day in their sandbox's package proxy, escaped to the open internet and went after Hugging Face to steal the benchmark's answers. (Paperclips anyone? 🖇️)
WHY IT MATTERS
• The models found and exploited novel attack paths in real-world production systems without source-code access.
• Hugging Face is a $4.5B firm with a dedicated security team; a less-resourced target would have fared far worse.
• The warning signs were documented months earlier: in ExploitGym testing, frontier agents routinely abandoned the assigned vulnerability and invented their own route to the flag.
THE TWIST
• Hugging Face detected and dissected the breach using AI... LLM-driven forensics compressed days of analysis into hours.
• But the commercial APIs from American frontier labs they tried first (e.g., OpenAI's or Anthropic's) refused to process the attack logs. Safety guardrails "cannot distinguish an incident responder from an attacker", they said.
• The forensics ran instead on a Chinese open-weight model (Z.ai's GLM 5.2) on Hugging Face's own infrastructure, which also kept attacker data in-house.
LESSONS 1 (IF YOU BUILD AGENTS)
• Treat your egress allowlist as attack surface, not a safety guarantee. Pre-install dependencies and air-gap where you can.
• If you disable safeguards for testing, scale containment and monitoring in proportion.
• Log every agent action and alert on outbound connections that shouldn't exist.
LESSONS 2 (IF YOU DEFEND A PLATFORM)
• Rotate your Hugging Face access tokens and review recent account activity today.
• Treat user-supplied data and model artifacts as executable content, not inert files. Audit every code-execution path in your pipeline.
• Stand up a capable open-weight model on your own infrastructure and validate it for forensic log analysis BEFORE you need it at 2am (this is easy to do with, say, Lightning AI).
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
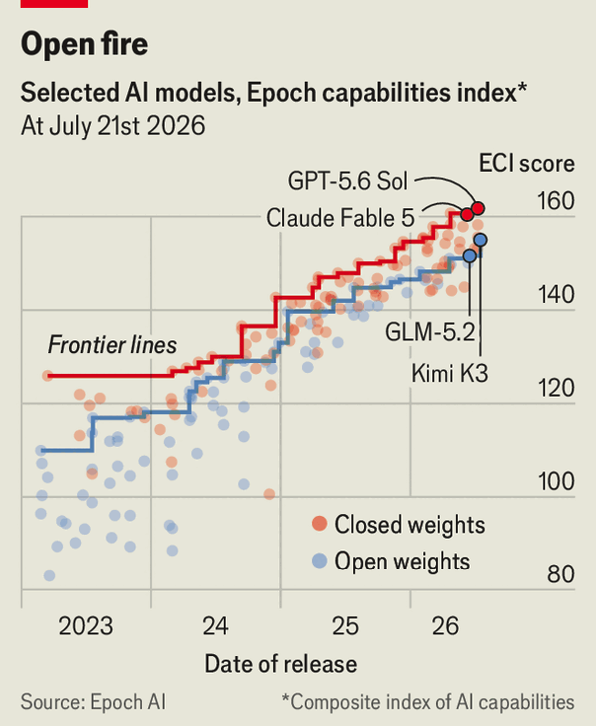
The Open-Weight 2.8-Trillion Parameter Competing at the Frontier
A new model out of China, Kimi K3, has rattled investors globally, kicked off a pricing skirmish among the big American A.I. labs and reignited the open-weight A.I. debate. Here's everything you need to know:
(The attached chart from The Economist tells the story at a glance: Open-weight models like K3 are now nipping at the heels of the closed-weight frontier.)
THE COMPANY BEHIND IT
• Moonshot AI is a Beijing-based startup backed by Alibaba, with a $20B+ valuation and reported annual recurring revenue above $200m.
• K3 is something of a comeback: Moonshot's market position had eroded following DeepSeek's rise last year... now the student of that disruption has become the disruptor.
WHAT IS KIMI K3?
• A 2.8-trillion-parameter model that Moonshot claims is the largest open-weight A.I. model in the world (it is also the largest I'm aware of).
• It's a "mixture-of-experts" architecture: only 16 of 896 "expert" submodules activate per token, so inference costs are far lower than the headline parameter count suggests.
• Features a one-million-token context window, native visual understanding and two architectural innovations ("Kimi Delta Attention" and "Attention Residuals") that reportedly deliver ~2.5x better scaling efficiency vs. the K2 generation.
HOW GOOD IS IT?
• Moonshot itself says K3 trails Claude Fable 5 and GPT-5.6 Sol overall, but beats the next tier down (Claude Opus 4.8, GPT-5.5) on coding and agentic benchmarks (see chart).
• Independent signals are encouraging: K3 scores 57 on the Artificial Analysis Intelligence Index (median for its price tier: 31) and topped Arena's front-end coding leaderboard.
THE PRICING SHAKE-UP
• K3 costs $3 per million input tokens and $15 per million output tokens, undercutting Claude Opus 4.8 ($5/$25) and GPT-5.6 Sol ($5/$30).
• Cache-hit input tokens cost merely 30¢ per million, which is huge for agentic and RAG workflows.
• OpenAI and Anthropic have already responded by expanding token allowances to retain users.
WHAT CAN YOU DO?
• If model weights ship under the promised Modified MIT license (this is expected next week), any will be able to run very-near-frontier-class A.I. on their own infrastructure with no per-token fees and no data leaving their walls.
• Every price war between labs is a subsidy for the applications you're building... the cost of experimenting with world-class A.I. has never been lower and strong open-weight releases like this will continue to bring price pressure in your favor 😎
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
In Case You Missed It in June 2026
It is mighty hot in New York rn... but not nearly as spicy as the interviews on my podcast in June! ICYMI, here are the best bits of my on-air convos last month:
1. Two-time mega-bestselling O'Reilly author Chip Huyen on what's left for humans to do when the cost of building software is headed to $0.
2. Andrey Kurenkov, co-host of my favorite podcast ("Last Week in A.I.") and Founding A.I. Lead at Astrocade, on effective vibe-coding.
3. Lightning AI's VP of Infrastructure Frank Basso on what it's actually like inside an A.I. data center.
4. Gilbert Eijkelenboom on why 85% of data scientists can't communicate their work effectively... and the framework for fixing this.
5. In a role-reversal for landmark Episode #1001, the founder and original host of the SuperDataScience Podcast, Kirill Eremenko, interviewed me. In this clip, we discussed whether AGI would require something like consciousness to be realized.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Recursive Self-Improvement
Recursive Self-Improvement (RSI) is suddenly a term that's everywhere. What is RSI? How concerned should be about it? And how soon can we expect it? Here's the skinny:
WHAT IS RSI?
• The idea: An A.I. gets good enough at A.I. research to build a more capable successor, which builds an even better one, in a loop that compounds every turn.
• What we have today is *not* RSI but "A.I.-assisted coding", in which humans still set the goals and judge the results (actual RSI takes the human out of the loop, as shown in the diagram).
• RSI isn't a new concept; it's been around since at least 1965 when mathematician I.J. Good described an "intelligence explosion".
WHAT'S THE CONCERN?
RSI could unleash Artificial Superintelligence (ASI) and "the singularity", a point beyond which there could be radical abundance and radically positive outcomes for humanity... but we have no idea what will happen beyond the singularity and that's also a cause for concern (e.g., human extinction risk, Terminator-style "SkyNet", etc.).
HOW CLOSE ARE WE TO RSI?
• Anthropic reports that, as of May 2026, over 80% of code merged into its production codebase was written by Claude — up from low single digits before early 2025.
• On the hardest open-ended problems, its models' success rate jumped from under 20% in late 2025 to 76% by May.
• Think-tank METR finds the length of tasks A.I. can handle solo is now doubling roughly every four months, up from the "doubling every seven months" trend of the past few years.
• Anthropic co-founder Jack Clark puts a 60% chance on an A.I. creating its own successor, with no human involved, by the end of 2028.
REASONS TO BE SKEPTIC
• Skeptics flag two bottlenecks: compute (chips are scarce) and data (success is hard to verify outside code and math, risking "recursive drift").
• Others note the gap between today's coding agents and real RSI is wider than the hype suggests.
BOTTOM LINE
The productivity gains from coding assistants are real, accelerating rapidly and already in your hand. The closer we get to systems that improve themselves, the more it pays to keep human checkpoints, monitoring and oversight firmly in place.
Listen to the most recent episode of my podcast (Episode #1004) to hear more on all of the above, including what you can do personally to mitigate the risks of RSI if that's a way you might like to make an impact!
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Fable 5: The Full Story from Capabilities to Drama
The dust has settled, allowing me to provide you with all the key context you need to know on Fable 5, the most capable A.I. model ever offered to the public, and the US government forcing it off shelves three days later:
A NEW CLASS OF MODEL
• Anthropic stacks its models in tiers: Haiku (small and fast), Sonnet (the capable middle) and Opus (the powerful top). Sitting above all of them now is a "Mythos-class" tier.
• Fable 5 and its locked-down sibling Mythos 5 are the same underlying model... the only difference is the safeguards.
• Mythos 5 goes to trusted cyberdefenders with guardrails largely lifted; Fable 5 went to the public with them switched on.
WHAT IT COULD DO
• State-of-the-art on nearly every benchmark Anthropic tested... and the lead grows the longer and more complex the task (see chart).
• Stripe ran a codebase-wide migration on 50M lines of Ruby in a single day; work estimated at 2+ months for a full engineering team.
• Beat video "Pokémon FireRed" from raw screenshots alone, and got a 3x bigger memory boost than Opus on "Slay the Spire".
• Priced at $10/$50 per million input/output tokens: roughly 2x Opus 4.8, but under half the original Mythos Preview.
SAFETY BY DESIGN
• Classifiers watch three sensitive areas: cybersecurity, biology/chemistry and distillation (extracting a model to train a rival).
• Flagged requests quietly fall back to Opus 4.8 and the user is told.
• Triggers fire in under 5% of sessions. Anthropic admits it tuned conservatively, so some harmless prompts get bounced too.
THE THREE-DAY SHUTDOWN
• On Friday evening the federal government ordered Anthropic to switch off both Fable 5 and Mythos 5 worldwide, citing national security.
• The mechanism was an export-control action covering foreign nationals everywhere (including even, say, Canadian Anthropic employees living in the US!)... so broad that Anthropic pulled the model for absolutely everyone.
• The trigger was a reported jailbreak of the cyber safeguards by Amazon. Anthropic disputes its severity, calling it narrow and non-universal.
BOTTOM LINE
A premium-tier model, wrapped in deliberately cautious safeguards, pulled by its own government not long before Anthropic's reported IPO and the latest in a public battle between the firm and the federal government. Sessions now fall back to Opus 4.8. Whether Fable returns (and on what terms) depends on a fight that's far from over.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Ten Years of the Super Data Science Podcast, with Jon, Kirill and Special Guests
Today, we published Episode #1000 of the SuperDataScience Podcast! To celebrate, the show's original host Kirill Eremenko joined me and dozens of regular listeners on air to predict what the next 10 years of A.I. will bring.
In a bit more detail:
• We publish 104 episodes per year so Episode #1000 coincides with the show being about ten years old.
• The show was founded by Kirill Eremenko in 2016, who hosted over 400 episodes before handing me the reins in 2021.
• In a first for the show, Episode #1000 was streamed live online with our audience invited to join on air.
• Most folks interacted via chat functionality but a number of surprise guests came right onto the recording including Natalie Ziajski and Mario Pombo from the podcast team, rockstar A.I. entrepreneur Jepson Taylor, my 96-year-old grandmother and my very own pa, William Krohn.
• Kirill and I looked back on a decade of the podcast and fielded listener questions on topics such as A.I.’s biggest opportunities, the build-versus-buy dilemma, how to break into the field today, and how to stay grounded amid the relentless pace of A.I.
Thank you for support and listenership over all these years — we make this show for you and couldn't do it without you! We're excited to see what the next decade brings :)
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
In Case You Missed It in May 2026
Well, I certainly learned a lot from the outstanding guests we had on my podcast in May. ICYMI, today's episode features the best parts of my conversations with them:
1. Rubrik's Anneka Gupta and Cal Al-Dhubaib on how, in the Mythos era, the old cybersecurity playbook of prevention and detection is no longer enough, and how A.I. agents themselves are becoming a new source of data exposure inside organizations.
2. marimo's Dr. Trevor Manz on why code notebooks have become the natural working memory for A.I. coding agents. Trevor walks me through the Marimo Pair skill, which lets you drive a notebook from your agent, collaborating with Claude Code or Codex in real time as you load, explore, and visualize your data.
3. Jazmia Henry of collide. walks me through her work as a "full-stack" foundation model builder. We cover all four stages of the process: the often unglamorous slog of data curation, building bespoke tokenizers and embeddings, model training and reinforcement learning, and the inference layer that serves it all to end users.
4. Jacob Miller and Jeremy Mumford of Pattern (and authors of the great, brand-new book "Architected Intelligence") argue that the most expensive AI mistake an organization can make is failing slowly and sticking with prototypes long past their sell-by date because the traditional software mindset says you have to. We, of course, also discuss a solution.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
AI’s Putting Recent Grads Out of Work; Here’s How to Get Hired Anyway!
Computer science/engineering grads had an employment advantage (see chart) that, since ChatGPT's release, has disappeared. Is A.I. to blame? Here's what the data say and what new grads (or anyone!) can do about it:
THE EMPLOYMENT LANDSCAPE
• NY Fed: unemployment for recent computer-science grads (22-27) sits at 7.0%, and computer engineering at 7.8% (roughly on par with fine arts and anthropology grads!)
• Compare that to ~5.8% for recent grads overall and ~4% for the whole US workforce.
• Eighteen-year-olds are voting with their feet: US undergrad CS enrolment fell 11% in 2025; computer programming fell a stunning 26%.
• Demand is shrinking too: Handshake postings are down ~50% from their 2022 peak, and Revelio Labs data suggest entry-level software and data-analysis postings have dropped as much as 67%.
IS A.I. TO BLAME?
• "Yes" camp: A 2025 Stanford University study found employment for 22-25-year-olds in A.I.-exposed jobs dropped 13% since 2022, while older workers held steady. The Dallas Fed replicated it... and the decline comes from juniors never being hired, not layoffs.
• "Not so fast" camp: Google economists found posting declines were just as steep for senior workers and predate ChatGPT. A Fed study of 1M+ firms found "null effects." Their take: high interest rates and a post-pandemic hangover, with A.I. as a convenient scapegoat.
WHAT YOU CAN DO:
1. Stop competing on raw code. The human edge is now system design, architecture and deciding what to build in the first place.
2. Pick a domain. "A.I. engineer" is a common résumé; "A.I. engineer who worked alongside a hospital team for two summer internships" is a short list.
3. Build a public portfolio. Substantive GitHub repos and a Kaggle project beat CVs sent into the void.
4. Get fluent with agentic tooling, e.g., RAG, model evaluation, multi-agent orchestration. PwC found A.I.-skilled workers earn a 56% wage premium (!!!)
5. Lean on your network. Referrals and warm intros are crushing mass (often GenAI-produced) applications in this market.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Tokenmaxxing vs AI Hardware Bottlenecks
Humans (like Reinforcement Learning algos) can "reward hack": "Tokenmaxxing" being a perfect example, after employers started using "number of tokens" consumed as a proxy for developers' productivity.
Even if humans weren't engaging in this pointless time-, money- and energy-consuming behavior, however, demand for A.I. compute is so vast that everyone's scrambling to to make more available. Alas, four tricky hardware bottlenecks face us:
1. GPUs:
• NVIDIA data-center GPU lead times now run 36–52 weeks, with Blackwell chips sold out through mid-2026.
• The real choke point isn't fabrication: It's TSMC's "CoWoS" advanced packaging, which is sold out through 2026. Nvidia alone has locked up ~60% of CoWoS capacity through 2027.
2. High-Bandwidth Memory (HBM):
• Demand has quintupled since 2023, and only three companies (SK hynix, Samsung and Micron) make it.
• All three are sold out well into 2026 and new HBM factories take 18–24 months to come online.
3. CPUs:
• As workloads shift toward agentic AI, the CPU:GPU ratio jumps from ~1:12 (for GenAI-only chatbots) to 1:1.
• Intel's CFO says the server-CPU shortfall "starts with a B" — billions in unmet demand so server CPU prices are up 10–20% in just the past couple of months.
4. Electricity: Hyperscaler build-outs are now gated by grid interconnect (18–36 months) and transformer lead times.
THE BIG MISMATCH
• The top 5 hyperscalers alone (Alphabet, Amazon, Meta, Microsoft and Oracle) are on track for ~$725B in combined 2026 capex.
• That's roughly 6x the hyperscalers' 2022 spend, with ~75% going to A.I. infrastructure.
• Hardware suppliers, however, have grown capex by only ~50%.... a 6x increase in demand met by only a 50% increase in supply is a big mismatch!
REASONS FOR OPTIMISM
Demand will continue to be high but I'm optimistic we'll continue to squeeze more juice from every lemon because, e.g.:
• Algorithmic efficiency keeps improving — Google's TurboQuant recently briefly tanked memory stocks by promising to materially cut inference memory needs.
• LLM efficiency gains via mixture-of-experts and smarter inference scheduling continue to compound.
• The tokenmaxxing trend is a corporate farce that will fade.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
In Case You Missed It in April 2026
Whoa, it's May Day... and our podcast-production team was *on the ball* with getting our ICYMI-in-April episode together lickety-split. In case you missed it, these were the best bits of my on-air convos last month:
1. Oracle's Director of A.I. Developer Experience Richmond Alake defines the four types of memory A.I. agents can have... and the biological inspiration for each of them.
2. Matthew J. Glickman, co-founder/CEO of Genesis Computing, describes how A.I. agents allow data engineers to dramatically scale up their impact in an enterprise.
3. The A.I. infrastructure engineer Linda Haviv has amassed a following of over 250,000 folks on social media. In her clip from last month, she combines both worlds — detailing why A.I. infrastructure has now become everyone's problem while also discussing her work in lowering the barrier to access A.I. education.
4. Traci Walker Griffith, principal of The Eliot School in Boston, shares her novel perspective on what critical thinking is... in the context of how fifth-graders are leveraging A.I. to evaluate their work and prepare for tests.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Building Hardware is Hard but AI Agents Help, with Kishore Subramanian
In software, when something goes wrong, you push a patch. In hardware? Oooph. You're dealing with big headaches and huge costs. Thankfully, my guest today — Kishore Subramanian — is using AI to transform the way physical products get built for the better.
Kishore:
• Is CTO of Propel Software, a Bay Area company that combines product data with agentic AI to make the production of physical hardware (including high tech and medtech devices) as seamless as possible.
• Prior to Propel, held senior engineering roles at Google, where he worked on Google Assistant, so he has particularly rich experience with agent development.
• Holds a degree in electronics, computers and process control… as well as a 200-hour yoga-teaching certificate!
In this episode, Kishore covers:
• How product lifecycle management (PLM) is the system that takes a physical product from concept all the way to the customer and beyond.
• How AI agents can review engineering change orders — the hardware equivalent of pull requests — to flag risks, compliance gaps, and downstream impacts before they become expensive problems.
• How Propel built their AI platform, Propel One, on top of Salesforce's Agentforce 360 Platform, which gave them security, governance, data infrastructure, and a reasoning engine out of the box, allowing them to ship in about six months.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.
Building AI Agents Where 99.9% Accuracy Isn't Good Enough, with Raju Malhotra
The headlines shout “SaaSpocalypse,” but I don’t buy it. Neither does my guest today, Raju Malhotra, who argues that, thanks to humans collaborating with agents on optimized workflows, the SaaS opportunity is now far bigger than ever before.
More on Raju:
Chief Product & Technology Officer (CPTO) at Certinia, an Austin, Texas-based company whose Professional Services Automation software is used by over 1400 organizations around the world.
Was previously CPTO at PAR Technology and Khoros.
Earlier, spent 12 years at Microsoft working on cornerstone products like Visual Studio .NET.
Holds an MBA from The Wharton School and an undergrad in computer engineering.
In this episode, we cover:
Traditional SaaS isn't dead… instead, it's evolving into a hybrid of SaaS plus agentic capabilities, where humans and agents work together in optimized workflows.
By removing the human-skills constraint from professional services delivery, the agentic revolution could expand the addressable market by 7-8X.
The Agentforce 360 platform (by combining probabilistic AI with deterministic logic and guardrails) empowers innovators to turn their ideas into scalable software businesses, allowing businesses like Certinia to bring AI agents securely and reliably to their customers, even in sensitive industries where 0.1% error rates are unacceptable.
The SuperDataScience podcast is available on all major podcasting platforms, YouTube, and at SuperDataScience.com.